Client name and some details and figures are changed to protect confidentiality under an NDA. The problem, the approach and the type of result are real.
Call transcripts written straight into your database stop the most expensive leak on a trading desk: the price, the promise and the next step that were said on a call and never written down. We built and shipped a local transcription and summary pipeline for a Vancouver commodity trading firm that picks up every call recording, transcribes it, summarizes it into the fields traders use, and writes the record into the firm's existing database. At cutover it ingested tens of thousands of calls with zero write errors.
Definition: call transcription to a database is the end to end process that fetches call audio, converts it to text, summarizes it into structured fields, and upserts that data into the system your team already works in, on a schedule.
The problem it solves
About 20 traders spent their days on the phone, and the details that decide a trade lived in recordings nobody had time to review. Notes were partial and late. Follow ups slipped because the next action was in someone's head. There was no searchable record for compliance, and every minute a trader spent writing notes was a minute off the calls that make the firm money.
| Step | Manual process | Automated process |
|---|---|---|
| Capture | Download recording. Rename files. | Watcher detects finished files and queues jobs. |
| Transcription | Upload to a service. Wait. | Speech to text runs locally. Jobs parallelize safely. |
| Summary | Trader writes notes, if there is time. | LLM converts the transcript to structured fields. |
| Filing | Copy into database screens. | Resilient writer upserts into the database with 3x retry. |
| QA | Spot checks when time allows. | Partial file guard, idempotency keys, error log, alerts. |
How the automation works
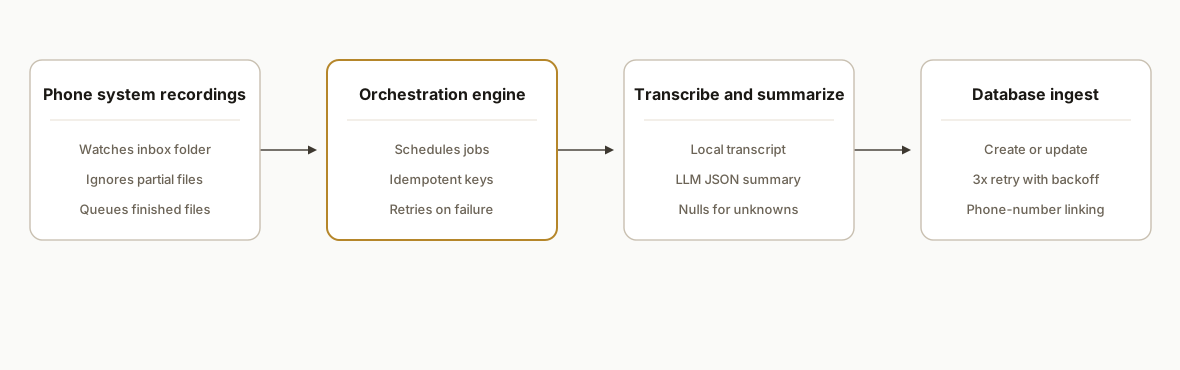
The pipeline runs on a local host for speed and data control. A downloader picks up recordings from the firm's cloud phone system. A queue orchestrator schedules jobs. A local speech to text model transcribes. A local LLM summarizes into structured fields. A database writer performs upserts with retries and phone number matching.
- Recording capture: a downloader monitors the recordings path and only releases files once they are fully written. Temporary partial files are ignored.
- Orchestration: a workflow engine schedules scans, fans jobs out to transcription workers, and gates retries. Jobs are idempotent via a call hash key.
- Transcription: a local model turns audio into timestamped text with speaker turns where available. This keeps costs predictable and throughput high.
- Summarization: a local LLM converts transcripts into meeting summaries and normalized fields like counterparty, instruments, and next actions.
- Database ingest: a writer maps each summary to the target table and performs create or update with backoff and 3x retry. Phone number matching links records to contacts.
Step by step: how to build it
1) Guard the recording intake and queue jobs
Only enqueue files once they are fully written to disk. Many phone systems write partial files with a temporary suffix while a download is in progress. The guard prevents broken transcripts and duplicate processing.
# watcher.sh
inotifywait -m -e close_write,create "$RECORDINGS_INBOX" | while read -r dir action file; do
  if [[ "$file" =~ \.mp3$ ]] && [[ ! -f "$dir/$file.temp" ]]; then
    # wait a beat in case the writer lingers
    sleep 2
    echo "{\"path\":\"$dir/$file\"}" | jq -cM > "$QUEUE_DIR/$(date +%s)-$file.json"
  fi
done
Key gotcha: always ignore any file that still carries a temporary suffix, and add a short post write delay.
2) Pin the orchestrator and workers
Run everything locally in containers so upgrades are controlled and compute sits close to storage. Pin every image version. We froze the workflow engine at a known good build because an upstream release renamed a trigger that the file watcher depended on.
3) Transcribe audio deterministically
Run transcription in a worker that reads queued jobs and writes JSON transcripts back to disk. Timestamped output helps downstream QA.
# transcribe.sh
set -euo pipefail
for job in $QUEUE_DIR/*.json; do
  AUDIO=$(jq -r .path "$job")
  BASENAME=$(basename "$AUDIO" .mp3)
  if [[ -f "$AUDIO" && ! -f "$OUT_DIR/$BASENAME.transcript.json" ]]; then
    ./transcribe-local "$AUDIO" --json "$OUT_DIR/$BASENAME.transcript.json"
  fi
done
Gotcha: keep a simple ledger to avoid reprocessing. The presence of a .transcript.json file is an easy idempotency guard.
4) Summarize to structured fields
A local LLM keeps speed high and cost flat. Be explicit in the prompt about the fields you need and what to do with low confidence items.
// summarize.js
export async function summarize(transcript, llm) {
  const prompt = [
    "Summarize this trading call. Return JSON with keys:",
    "counterparty, participants[], instruments[], summary, next_actions[], call_datetime, phone_e164",
    "Be factual. If unknown, use null not a guess."
  ].join("\n");

  const text = await llm.generate(`${prompt}\n\n${transcript}`);
  return JSON.parse(text.match(/\{[\s\S]*\}/)[0]);
}
Guardrail: require null for unknowns so database fields do not fill with hallucinations.
5) Upsert into the database with retries
Write a small wrapper that maps your JSON to the target table and retries transient failures. We used 3 attempts with exponential backoff.
// db-writer.js
export async function upsertCall(record, client) {
  const max = 3;
  let attempt = 0;
  while (attempt < max) {
    try {
      await client.upsertRecord({
        table: process.env.TARGET_TABLE,
        matchKey: hashKey(record), // e.g., audio filename hash or call_id
        fields: {
          call_datetime: record.call_datetime,
          phone: record.phone_e164,
          counterparty: record.counterparty,
          summary: record.summary,
          next_actions: record.next_actions?.join("; ") || null
        }
      });
      return true;
    } catch (e) {
      attempt++;
      if (attempt >= max) throw e;
      await new Promise(r => setTimeout(r, 500 * Math.pow(2, attempt)));
    }
  }
}
Two details matter: a stable match key so replays dedupe cleanly, and backoff so a busy server does not drop writes.
6) Link calls to contacts by phone number
Normalize to E.164 and match against contact records. This keeps summaries attached to the right person without relying on filenames.
# phone_match.py
import phonenumbers

def to_e164(raw, region="CA"):
    try:
        p = phonenumbers.parse(raw, region)
        if phonenumbers.is_valid_number(p):
            return phonenumbers.format_number(p, phonenumbers.PhoneNumberFormat.E164)
    except Exception:
        return None
    return None
Gotcha: mixed local formats create false negatives. Normalize every phone field going into the database and during matching.
Where it gets complicated
- Partial files: phone systems often write temporary files while a recording downloads. Transcribe those and you get corrupt text. Only enqueue finished files and add a small post write delay.
- Database writes need retries: even healthy servers occasionally refuse a write under load. A 3x retry with backoff made writes reliable in production.
- Phone number hygiene: matching on numbers only works when everything is in the same format. Normalize all numbers to E.164 on ingest and in the database.
- Orchestrator churn: pin the workflow engine at a known good build. Upstream releases rename things, and a renamed trigger silently stops the watcher.
- Privacy and discoverability: once every call is transcribed and indexed, sensitive remarks become searchable. Set retention, access, and audit policies before go live.
What this actually changes
Every trader call now lands in the firm's database with a transcript, a summary, and next actions. At cutover the system ingested tens of thousands of calls with zero write errors. The money is in what stops leaking: follow ups that happen because the next step is written down, deal details nobody has to reconstruct, and a searchable record for compliance and audits.
The principle applies to any firm whose revenue is decided on the phone. If the details of a call only exist in a recording and a person's memory, some of that revenue is already slipping.
One external anchor: knowledge workers spend on the order of 19 percent of their time searching for information and another 14 percent communicating internally, per the McKinsey Global Institute report The social economy.
Frequently asked questions
Can call summaries go into the database we already use?
Yes, as long as it accepts programmatic writes, which most modern business databases do. We map summaries to a target table and perform create or update operations with retries. You do not need to screen scrape the user interface to keep it in sync.
Can this run entirely on premises for data control?
Yes. We ran the downloader, orchestrator, transcription, and summarization locally. Audio and transcripts stayed on the client's network. The only writes went to the database server inside the same environment.
How do you prevent duplicates if a recording is downloaded again?
We compute a stable match key per call, such as a hash of the audio filename and timestamp or a call identifier from the phone system. The writer performs an upsert keyed on that value, so replayed jobs update the same record rather than creating a new one.
Is this real time or batch?
Our deployment ran near real time for new recordings, with a short delay for file finalization and transcription. You can also schedule hourly or nightly batches if compute is shared across teams.
What does this cost to operate monthly?
Transcription and summarization ran on local compute, so recurring costs were minimal. Your real cost is the server and storage you already maintain. If you choose hosted transcription or model APIs, add their usage fees on top. We designed the stack to keep those optional.
Can a non developer maintain this after handoff?
Yes. We pinned versions, documented the flows, and added clear logs. Typical operator tasks are restarting containers, checking the queue folder, and reviewing any failed write alerts. Changing field mappings should go through a developer.
If your revenue is decided on calls and you want every one captured in the system you already run, we have already built and shipped this. Read the commodity trading case study, see our document automation services, or book a 20 minute call and we will map your environment in the first five minutes.
Sources
- 1.McKinsey Global Institute report The social economymckinsey.com
Want us to build this for you?
Nine questions, about 90 seconds. You see the revenue it is costing you, then pick a time. No pitch.
See your options